Medical Cabinet: an NLP strain recommender
TF-IDF and nearest neighbors over 2,350 strain descriptions, served by a Flask app. A BloomTech (Lambda School) project.
2026 note: Written during BloomTech (then Lambda School). The Heroku app it originally linked to went offline when Heroku ended its free tier, so links now point to the code. Looking back, nearest-neighbor search over document vectors is the same retrieval idea behind today’s RAG systems. I later proposed pre-trained embeddings with nearest-neighbor search to teams I led.
My humble thoughts on the project before you dive deeper
As a note to anyone reading this, I do not use or have a need to use Marijuana. I respect anyone’s opinion to use this plant as a medicine or otherwise. I hope that this small blog post will be useful to those interested in understanding how I built my flask APP on Cannabis-API-2.
This project is pretty simple but makes use of some very cool NLP(natural language processing) techniques. I hope to make use of more advanced NLP in the future like I did with the next project I worked on. I will outline how I built the HTML front end and how the model that makes the predictions was built.
If you have any questions please feel free to send them to me and I will do my best to answer them.
You can find the code I used here
Enjoy!
The data I used to make the model
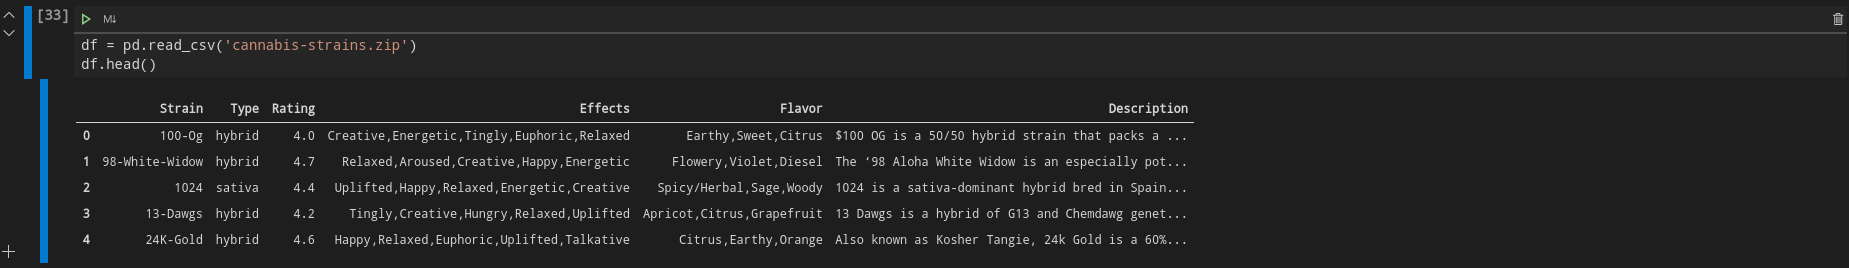
This dataset comes from kaggle, kindly provided by leafly.
It contains 2350 unique strains with their corresponding type(Hybrid, Indica, Sativa), rating(0.0-5.0 by users), Effects(Uplifted, Happy, Relaxed, etc.), taste(of smoke), and a description(brief, about the plants background).
Preprocessing the dataframe
We first begin by replacing the ‘NaN’ values with ‘None’
1
df = df.fillna('None')
Then proceed to make a ‘bag of words’ from all the rows
1
df['bag_of_words'] = df['Strain']+" "+df["Effects"] +" "+ df["Flavor"] +" "+ df['Description'] +" "+ df['Type']
We continue by making this column in the data frame into tokens
1
2
3
4
5
6
7
8
tokens = []

""" Make them tokens """
for doc in tokenizer.pipe(df['bag_of_words'], batch_size=500):
    doc_tokens = [token.text for token in doc]
    tokens.append(doc_tokens)

df['tokens'] = tokens
Making the model
We first need to vectorize and incidentally remove the stop words as well
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
from sklearn.feature_extraction.text import TfidfVectorizer

# Instantiate vectorizer object
tfidf = TfidfVectorizer(stop_words='english')

# Create a vocabulary and get word counts per document
#Similar to fit_predict
dtm = tfidf.fit_transform(df['bag_of_words'])

# Print word counts

# Get feature names to use as dataframe column headers
dtm = pd.DataFrame(dtm.todense(), columns=tfidf.get_feature_names())

# View Feature Matrix as DataFrame
dtm.head()
Create the nearest neighbors model
1
2
3
4
5
6
7
8
# Instantiate
from sklearn.neighbors import NearestNeighbors
from sklearn.feature_extraction.text import TfidfVectorizer


# Fit on TF-IDF Vectors
nn  = NearestNeighbors(n_neighbors=5, algorithm='kd_tree')
nn.fit(dtm)
Predict Function
Now that we have the model created and pickled we can make a function that we can use in our predict file.
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
def recommend(text):
   # Transform
    text = pd.Series(text)
    vect = tfidf.transform(text)

    # Send to df
    vectdf = pd.DataFrame(vect.todense())


    # Return a list of indexes
    top5 = nn.kneighbors([vectdf][0], n_neighbors=5)[1][0].tolist()


    # Send recommendations to DataFrame
    recommendations_df = df.iloc[top5]
    recommendations_df['index']= recommendations_df.index

    return recommendations_df
Please refer to the notebook if you need more information
The packages I used for this app are:
1
2
3
4
5
6
7
8
9
flask
python-dotenv
python-decouple
gunicorn
pandas
sklearn
numpy
joblib
spacy